 Computer Forum
 Gemma 4 31B lokal (Image © Google)
Versatile Models for Different Hardware
Gemma 4 is available in four sizes: Effective 2B (E2B), Effective 4B (E4B), 26B Mixture of Experts (MoE), and 31B Dense. These models are optimized to deliver state-of-the-art inference on a wide range of hardware, from mobile devices to PCs. This makes them well-suited for local operation on your own hardware.
- 26B and 31B models: Deliver top-tier intelligence on common hardware, with the unquantized bfloat16 weights fitting efficiently on a single 80-GB NVIDIA H100 GPU.
- E2B and E4B models: These models were designed for maximum computational and memory efficiency and effectively use 2 billion and 4 billion parameters, respectively, during inference, thereby conserving RAM and battery life on mobile devices.
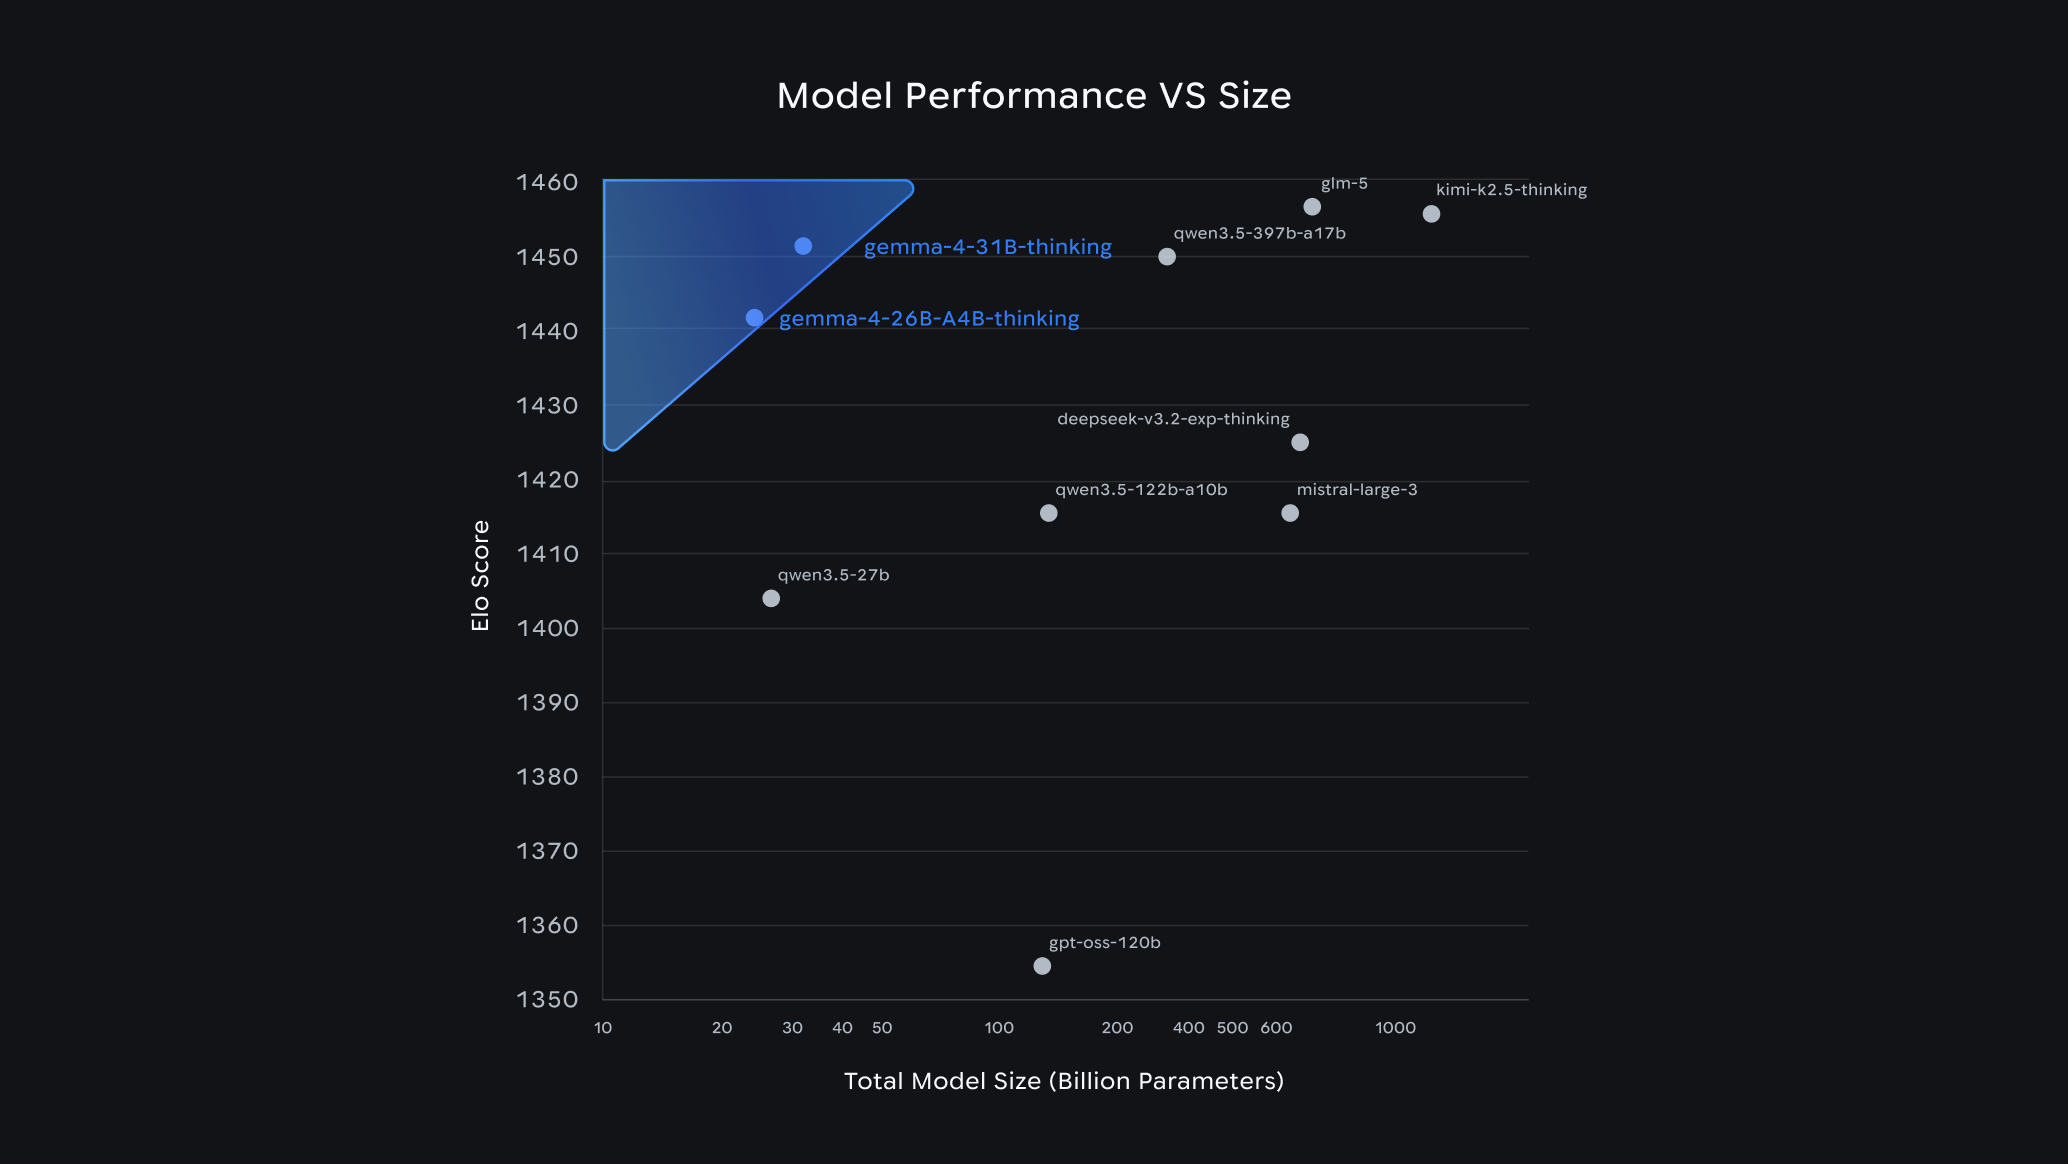 Gemma 4 Perofrmance (Image © Google)
Open-Source License and Security
Gemma 4 is released under a commercially permissible Apache 2.0 license, offering developers complete flexibility and digital sovereignty. This open-source license grants control over data, infrastructure, and models, enabling secure deployment in any environment. The models undergo rigorous infrastructure security protocols, ensuring a trustworthy and transparent foundation that meets the highest standards for security and reliability.
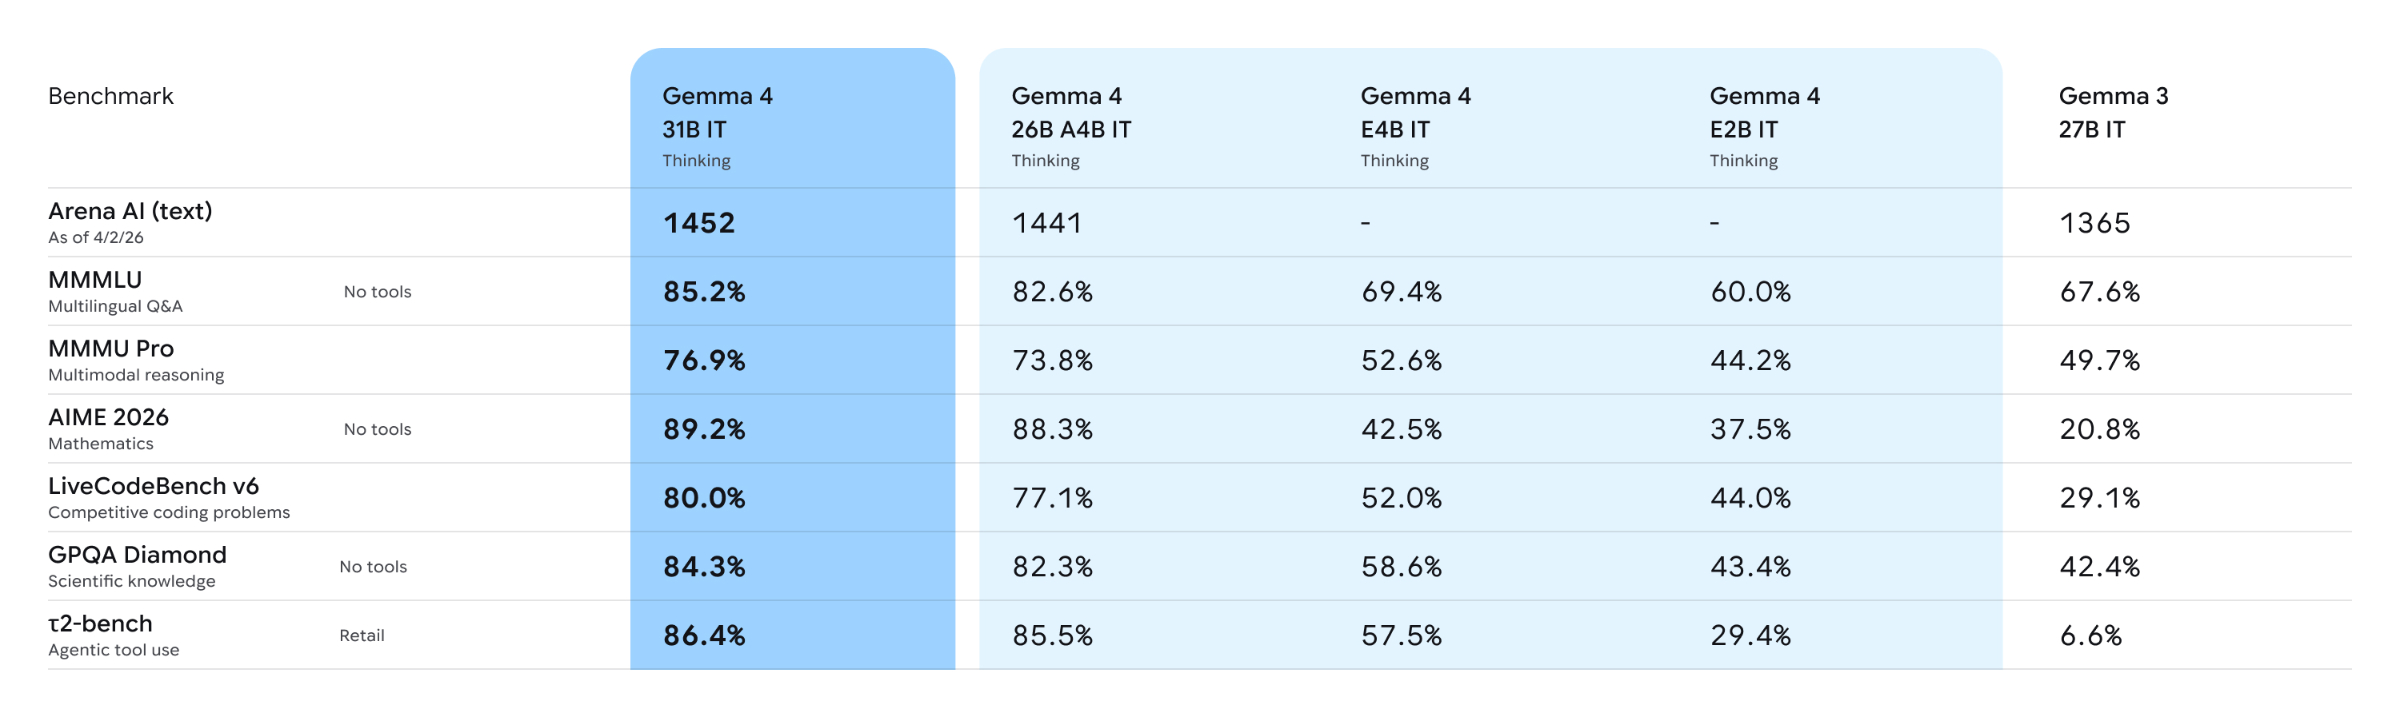 Gemma 4 Vergleich (Image © Google)
Industry-Leading Performance
Gemma 4 has achieved remarkable results on industry-standard benchmarks: The 31B model currently ranks third among the world’s best open models on the Arena AI Text Leaderboard. The 26B model has secured 6th place, outperforming models 20 times its size. These groundbreaking capabilities are accessible to everyone and enable developers to push the boundaries of AI innovation.